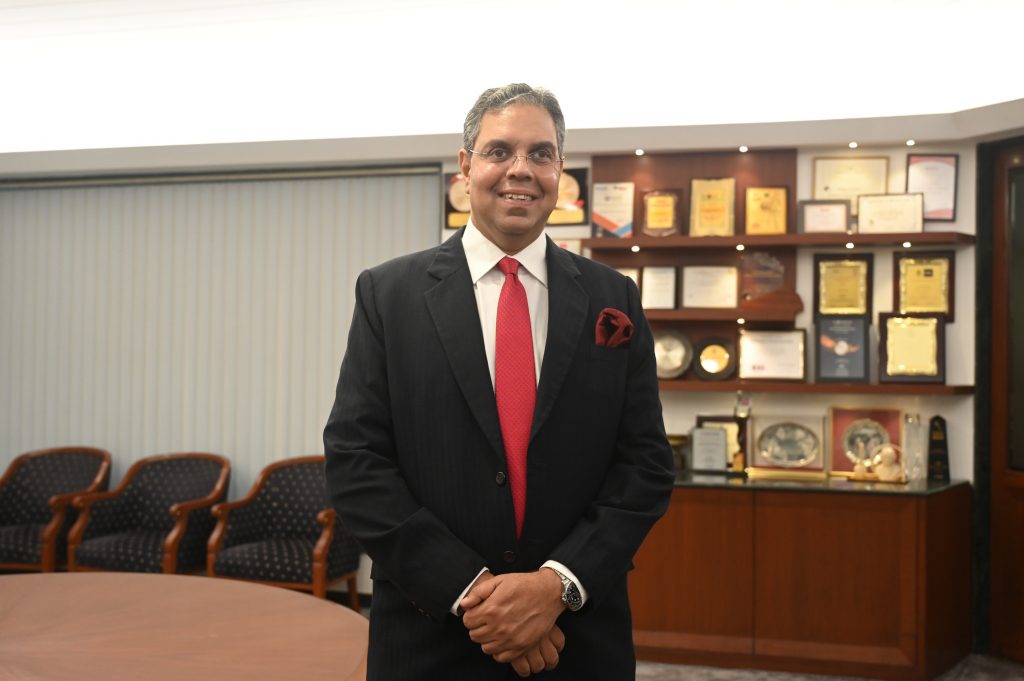
Companies are pouring money into enterprise AI tools and infrastructure, yet poor data quality continues to undermine results. In digital commerce, the damage is visible: incomplete attributes hide products from search, inaccurate specifications drive returns, and customer trust erodes. In this conversation with CIO&Leader, Sameer Kanodia, Vice Chairman and CEO of Lumina Datamatics and TNQTech, explains why data quality the biggest bottleneck to AI success is and why it is still treated as a backend function. He discusses where AI is making the biggest difference in product data management, how to catch confident but incorrect outputs before they reach live catalogs, where human judgment must remain, which metrics connect data quality to business outcomes, and how leaders should prepare today.
CIO&Leader: Companies are investing heavily in AI tools and infrastructure, yet poor data quality continues to hinder results. Why is data quality the biggest bottleneck to AI success and why is it so often underestimated?
Sameer Kanodia: AI systems are only as effective as the data they can access and interpret. Businesses may invest in advanced models and infrastructure, but if their underlying data is fragmented, incomplete, or inconsistent, the output will reflect those limitations.
Data quality is often underestimated because it is viewed as a backend function rather than a business priority. Organizations tend to focus on deploying AI and automating processes without first establishing whether their data is reliable.
In our work across content and data management, we have seen that establishing a consistent data structure is often the first step towards making AI-driven workflows effective. Businesses need to recognize that data quality is not a one-time exercise but an ongoing requirement for successful AI adoption.
CIO&Leader: In digital commerce, what does “bad data” look like, and what does it cost a brand or retailer in terms of lost product discovery, increased returns, and diminished customer trust?
Sameer Kanodia: In digital commerce, bad data includes incomplete product descriptions, incorrect specifications, missing attributes, inconsistent categorization, and outdated images. These gaps directly affect how products appear in search results and how customers evaluate them.
For instance, if a customer is searching for footwear with a specific material or size, incomplete product attributes may prevent relevant products from appearing in search results. Similarly, inaccurate dimensions or product specifications can lead to purchases based on incorrect expectations, increasing the likelihood of returns.
We work with global retailers on product data management and catalog optimization, focusing on ensuring product information is accurate, enriched, and consistent across platforms. As digital commerce becomes increasingly competitive, catalog accuracy needs to be treated as a business priority rather than simply a listing requirement.
CIO&Leader: Product data management has traditionally been a manual process. Where is AI making the biggest difference today—in classification, enrichment, or validation?
Sameer Kanodia: AI is making a difference across all three areas, but product data enrichment is particularly valuable because it helps convert basic product information into structured, searchable and relevant content.
AI can analyze product descriptions and images, identify missing attributes, generate metadata and support product classification. It can also validate information against predefined standards and marketplace requirements.
We are increasingly using AI-driven capabilities to support classification and enrichment across large product catalogs, while retaining human quality checks. The objective is not just to process more SKUs faster, but to ensure that the information being published is accurate and useful. The greatest value comes when classification, enrichment, and validation work together as part of one integrated workflow.
CIO&Leader: Why do structured and enriched datasets make enterprise AI more reliable? Can you share an example of how the same AI system can produce significantly different results when working with clean versus messy data?
Sameer Kanodia: Structured data gives AI the consistency and context required to interpret information correctly. Without it, even a well-designed AI system can generate irrelevant or inaccurate outputs.
Consider an eCommerce recommendation system. If product information includes standardized attributes such as material, size, category, and compatibility, the system can identify products that closely match a customer’s requirements. However, if these attributes are missing or inconsistently recorded, the same system may overlook relevant products or recommend unsuitable alternatives.
In our experience, bringing fragmented product information into standardized structures makes it more useful across commerce platforms and digital workflows. Hence, data standardization and enrichment are important parts of enterprise AI adoption.
CIO&Leader: What are the most challenging technological hurdles in applying AI to large, complex product catalogs across multiple platforms and marketplaces?
Sameer Kanodia: The biggest challenge is that different marketplaces follow different taxonomies, attribute requirements, and content standards. A product listing that meets the requirements of one platform may need significant changes before it can be published on another.
Retailers often manage millions of SKUs, with information coming from multiple suppliers and systems in different formats. The scale of catalogs adds to this complexity. Keeping this information accurate and synchronized across channels requires robust data architecture and continuous validation.
Our experience working with large product catalogs has shown us that technology needs to be supported by taxonomy mapping, automated validation, and domain expertise. The focus is on ensuring that automation can scale without compromising the accuracy and consistency of product information.
CIO&Leader: How can businesses integrate AI into existing workflows without introducing inconsistencies or disrupting teams that follow established processes?
Sameer Kanodia: Businesses should adopt AI incrementally rather than attempt to replace existing workflows entirely. They can begin by identifying repetitive activities, such as product classification, metadata creation, and data validation, where automation can improve efficiency while existing approval processes remain in place.
Technology integration is equally important. AI solutions should work with existing content management and product information systems rather than create disconnected processes.
Our approach includes modular, API-first platforms such as XEditPro and BluPencil, which allow clients to modernize workflows without replacing their entire technology infrastructure. This helps organizations introduce automation at their own pace while retaining control over quality, processes, and decision-making.
CIO&Leader: AI can generate incorrect product attributes with a high degree of confidence. How can businesses identify and correct these errors before they make their way into live catalogs?
Sameer Kanodia: Businesses need to distinguish between AI-generated information and verified information. An output may appear accurate, but it should not be published without appropriate checks.
AI-generated attributes should be checked against reliable sources such as manufacturer specifications and approved product feeds. Systems should also flag missing information, conflicting values, and deviations from marketplace requirements. This requires a combination of automated validation and human review.
Our approach combines AI-led processing with human quality checks to ensure that information is reviewed against defined standards before publication. As AI adoption increases, organizations will need to invest as much in validation frameworks as they do in content generation and automation.
CIO&Leader: Where should human intervention remain essential, and where is full automation a safe option for ensuring data quality? How is this balance likely to evolve as AI models improve?
Sameer Kanodia: Automation is most effective for repetitive, rule-based activities such as identifying missing attributes, standardizing formats, detecting duplicates, and applying predefined classification rules.
Human intervention remains essential when decisions require contextual understanding, domain expertise or judgment. For instance, resolving conflicting product specifications or determining whether a particular attribute accurately represents a product may require specialist knowledge.
We believe the most effective model is a combination of AI capabilities and human expertise. As AI models improve, more routine activities will become automated, allowing teams to focus on exceptions, complex decisions and quality assurance. The future will be defined by how effectively businesses combine the scale of automation with human judgment.
CIO&Leader: Beyond speed and cost savings, how should businesses measure the value of AI-led data management? Which metrics most directly connect improvements in data quality with business outcomes, and how should leaders prioritize them?
Sameer Kanodia: Businesses should measure the impact of AI-led data management at both the operational and commercial levels. At the data level, metrics such as attribute completeness, accuracy, duplicate rates, and the percentage of listings passing validation provide a clear indication of data quality.
These improvements should then be connected to business outcomes, including product search visibility, click-through rates, conversion rates and product returns linked to incorrect information. Businesses should also track catalog onboarding time and the extent of manual corrections required.
In our work with retailers, the focus is on improving product information quality and discoverability through AI-driven catalog management. The real measure of success is not simply how much information can be processed, but whether better data helps businesses improve the customer experience and commerce performance.
CIO&Leader: Looking ahead over the next three to five years, how will enterprise data management and intelligent automation evolve, and what should business leaders do today to prepare for stronger data quality?
Sameer Kanodia: Over the next three to five years, enterprise data management will become increasingly predictive and automated. AI systems will move beyond processing information to identifying inconsistencies, recommending corrections, and helping businesses respond to changing requirements.
In eCommerce, this could lead to more adaptive product catalogs that respond to changing consumer preferences, regional requirements and marketplace standards. We also expect greater integration between AI platforms and enterprise systems, making information more accessible across business functions.
We are investing in AI-driven platforms and solutions that support this shift across publishing and retail workflows. However, businesses need to prepare by establishing standardized data structures, strengthening governance, and investing in technology that integrates with existing systems. The competitive advantage will come from combining reliable data, intelligent automation, and domain expertise.