AI at scale demands stronger data, architecture, governance and cost discipline.
As enterprises move AI from experimentation into operational environments, the technology challenge is shifting from model selection to the infrastructure surrounding those models. Data freshness, streaming architecture, governance, cost optimisation and deployment flexibility are becoming critical to whether AI can deliver measurable business value.
The integration of Confluent into IBM’s data and AI portfolio brings these issues together, combining streaming, processing, governance and orchestration capabilities. For Indian enterprises, the questions are particularly relevant as digital-native companies scale rapidly, regulated sectors contend with data sovereignty, and CFOs increasingly scrutinise technology spending.
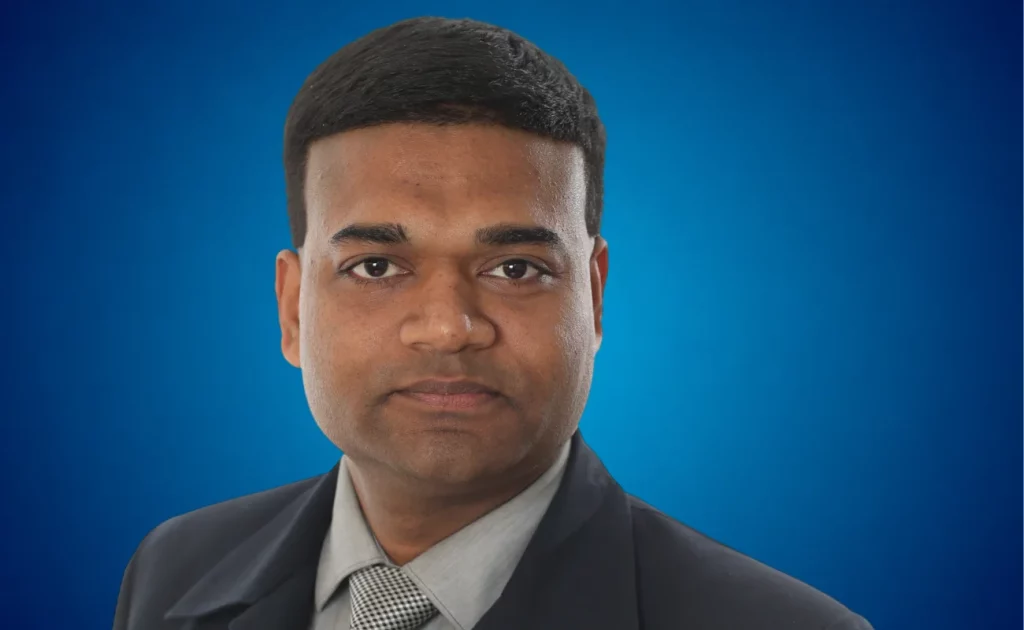
In this interview, Rohit Vyas, Director, Solutions Engineering, Confluent discusses how enterprises can build connected data architectures, manage AI and streaming economics, secure distributed environments and determine when focused AI models may be more appropriate than large language models.
CIO&Leader: What does Confluent’s integration into IBM mean for the broader data and AI architecture?
Rohit Vyas: The business integration happened on 17 March and has been working very well. We are in the first year of the integration, and Confluent is now part of IBM’s data and AI vertical.
A significant development is that Sean Klaus, formerly Confluent’s chief product officer, is now the general manager not only of the Confluent portfolio but also of IBM’s broader data practice. A much larger product engineering organisation, including IBM teams, now reports to him to build the next generation of IBM’s data portfolio.
That demonstrates the confidence IBM has in what Confluent has built in the data infrastructure category.
IBM already has the WatsonX portfolio covering areas such as orchestration, data lakes and governance. Confluent becomes a natural partner within that environment. Confluent handles ingestion, aggregation and integration; Flink provides processing; WatsonX provides governance and orchestration; and WatsonX Data provides the data lake layer.
The result is a more comprehensive data and AI pipeline.
The objective is also to prevent the data lake from becoming another isolated silo. Whether data sits in operational transaction systems or analytical environments, Confluent acts as a common fabric between them, allowing organisations to maintain freshness and quality as data moves across transactional, analytical and AI environments.
CIO&Leader: Digital-native companies often scale faster than their infrastructure. What changes when an organisation moves from open-source Kafka to enterprise-scale streaming?
Rohit Vyas: This is an important part of our India business, which has grown by more than 70% year on year, with a large part of that coming from digital natives.
Before an IPO, many of these companies are technology builders rather than traditional technology buyers. They are bootstrapping, trying to do more with less and moving quickly, so open source is a natural choice.
Kafka is widely adopted for data streaming. But open source remains free only until you download it. After that, you have to deploy, maintain and scale it.
There is also a provisioning problem. Open-source Kafka has to be prepared for the worst possible traffic scenario. Digital-native companies typically have peaks during the year, so they end up provisioning for the peak even when that capacity is not being used.
Then comes the question of enterprise readiness. As companies approach or move beyond an IPO, they have to demonstrate that their infrastructure is secure, resilient and performant and that they can provide appropriate support.
A managed service allows infrastructure to flex with traffic. Customers pay for what they use and get enterprise-grade resilience, support and a product roadmap.
Eternal, for example, is running approximately 4 GB per second of traffic on WarpStream, a bring-your-own-cloud model. At that scale, operating open source while maintaining a lean organisation can require significant operational resources. Managed infrastructure allows digital natives to keep more people focused on innovation.
CIO&Leader: AI spending is also facing greater CFO scrutiny. Where can enterprises find meaningful savings in the data infrastructure stack?
Rohit Vyas: Our market assessment and customer observations indicate that customers using data lakes can spend 40–70% of the cost on ingestion and transformation. ETL and ELT pipelines can therefore represent a significant portion of the overall data-lake spend.
There is another differential. If a customer spends X on streaming technology, it can typically spend around 10X on data-lake technology. That creates an opportunity for streaming to reduce unnecessary data movement and transformation costs.
One of our large international customers in the tobacco business, a significant Snowflake user, moved governed transformation out of its data lake and, according to the customer, achieved double-digit-million-dollar savings in the first year.
I would not position streaming as a replacement for the data lake. The data lake has its own value. Streaming complements it by reducing unnecessary costs and making the data lake more effective.
There is also an AI benefit. Streaming provides fresher data, allowing AI systems to work with more current information rather than relying entirely on batches.
CIO&Leader: You have argued that the biggest AI challenge is the data flow rather than the model itself. What does that mean in practical terms for enterprises deploying generative AI and agents?
Rohit Vyas: AI’s problems have never primarily been the problems of the LLM. Foundational and frontier models have become quite mature. The bigger challenge is the data flow.
If you cannot get real-time data to AI, its usefulness is limited. Generative AI will always have some level of hallucination, but when you provide current and governed data, you can control that risk much more effectively.
AI’s problems have never been the LLM’s problems. AI’s problems are data flow problems.
For retrieval-augmented generation and agentic environments, systems need current context. AI is essentially software talking to software, and that interaction needs to be real-time and well orchestrated.
Confluent can ingest, connect, govern and transform data for AI, while WatsonX provides governance and orchestration. The objective is to create a connected pipeline into AI rather than treating the model as the entire architecture.
There is also a cost consideration. Enterprises are increasingly using multiple LLMs because they have different capabilities and cost structures. Not every interaction requires the most expensive model.
The business context should determine which model is appropriate. That choice requires access to the right data and context. This is another area where the data infrastructure can contribute directly to AI cost optimisation.
CIO&Leader: As AI and data environments become more distributed, how should regulated enterprises approach deployment, data sovereignty and security responsibility?
Rohit Vyas: Data sovereignty is extremely important, particularly when dealing with personally identifiable information at citizen scale.
Customers across public sector, financial services and digital-native environments have a range of deployment options. They can choose completely self-managed, cloud SaaS, bring-your-own-cloud or hybrid architectures.
If an organisation operates in a strict air-gapped environment, it can use Confluent Platform. If it wants cloud infrastructure while maintaining sovereignty within India, it can choose a cloud region in the country. With BYOC, the customer’s data remains within its environment while the control plane operates in the cloud.
Hybrid is another option. We have a banking customer in Mumbai that keeps PII on premises while running analytics in the cloud.
The principle is choice, but responsibility changes with that choice.
In a completely self-managed environment, the customer controls the security posture and is responsible for threat assessment, modelling and mitigation. Confluent remains responsible for areas such as patching, updates and the security posture of its software.
With BYOC or hybrid, responsibility is shared. With SaaS, more responsibility sits with Confluent, although the customer retains control over authentication, authorisation and access.
The division of responsibilities is clearly defined contractually. We also work closely with CISOs and information security teams to understand regulatory requirements and recommend an appropriate deployment model.
CIO&Leader: What capabilities are becoming particularly important for Indian enterprises as they balance on-premises infrastructure, cloud and AI workloads?
Rohit Vyas: Hybrid architecture is becoming increasingly important. One area we are doing more work around is Confluent Private Cloud, which allows customers that have traditionally operated fully on-premises and self-managed environments to introduce a cloud-based control plane if they choose.
It can also support data-centre-to-disaster-recovery and failover high-availability scenarios.
Another area is Tableflow, which makes Kafka integration with data lakes through Iceberg easier. We are also seeing Indian digital-native cloud users increasingly gravitating towards GCP, and we are bringing Tableflow support to that environment.
We are continuing to expand connectors and deepen integration with WatsonX. Another interesting area is IBM Granite, particularly smaller foundational models designed for tasks such as anomaly detection and forecasting.
Through our work with IBM, we are looking at putting these models inside Flink so forecasting and anomaly detection can happen at scale within the streaming environment.
That brings AI capabilities closer to the data and the business process.
CIO&Leader: Does the growing interest in smaller models mean enterprises should rethink their pursuit of large language models?
Rohit Vyas: I would not describe it as a binary choice between LLMs and SLMs. It is about expanding the horizon of choice.
Not every enterprise use case requires an LLM. Problems such as anomaly detection, inventory forecasting, inventory management and pattern identification can be better suited to smaller, focused foundational models.
Rather than a zero or one shift, it has to be expand the horizon of choice.
The first step should therefore be identifying the use case.
For these applications, smaller models can be more cost-effective and do not necessarily require GPUs. IBM Granite models, for example, have performance numbers for both CPUs and GPUs, allowing enterprises to make infrastructure decisions based on throughput and cost.
The important point is that the technology should be selected according to the problem being solved.
For a focused use case, an SLM can be more effective than an LLM because it is trained for a narrower purpose and can require fewer resources. It can also reduce the potential for irrelevant or unpredictable outputs.
So the question is not whether enterprises should abandon LLMs. It is whether they are choosing the right model, data architecture and infrastructure for each business problem.
That is ultimately where enterprise AI is heading. The value will not come simply from deploying the largest model available. It will come from connecting the right data, architecture, model, governance and infrastructure to the business outcome the organisation is trying to achieve.